How to Evaluate RAG Retrieval With Recall@k and MRR
A documentation assistant gives an incomplete answer about account sharing. Before rewriting its prompt, check whether the search step retrieved both the permissions guide and the limits page. If one is missing, the model never received the evidence you expected it to use.
This tutorial builds a small retrieval check with labeled document IDs, Recall@k, and mean reciprocal rank. The Python example runs locally without a model, vector database, or API key. It grades supplied rankings; it does not run a search engine or measure a production RAG system.
1. Decide what counts as useful evidence
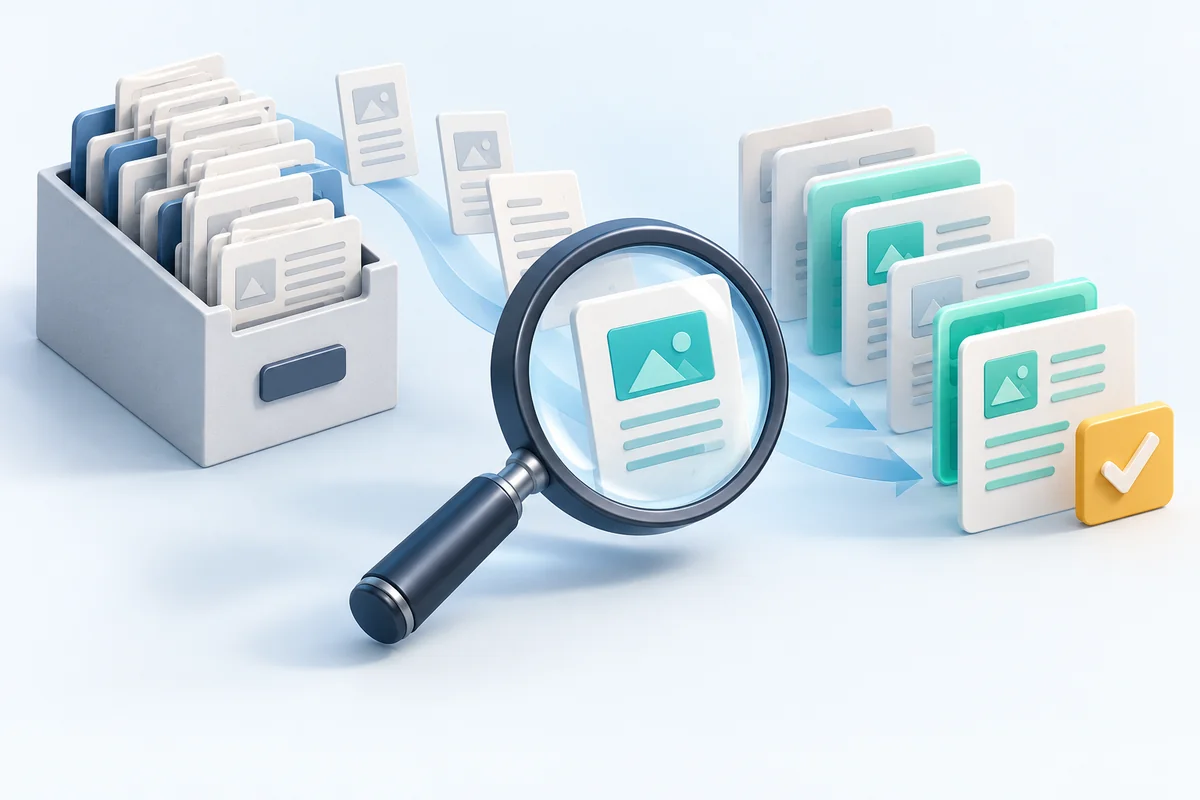
Pick one collection, such as your product documentation, and freeze a version for the test. Give each retrievable item a stable ID. Decide whether an item means a whole document or one chunk; use the same unit in both the labels and the search results.
For a first development set, write a few dozen questions drawn from the work your assistant should handle. That is an editorial starting point, not a statistically justified sample size. Review the evidence manually and include questions requiring more than one source.
A tiny illustrative set looks like this:
| Query ID | Question | Relevant document IDs |
|---|---|---|
| q_export | How do I export a CSV? | export_csv |
| q_reset | How do I reset access, and what restrictions apply? | reset_steps, reset_limits |
| q_sharing | Who can share an account, and what limits apply? | share_roles, share_limits |
Record why each item is relevant and which collection version the reviewer inspected. An answer that merely repeats the question is not evidence. Do not let the retriever being tested define its own answer key.
If you change chunk boundaries, review the labels before comparing scores. A new chunk ID scheme can break an otherwise valid evaluation.
2. Read Recall@k and MRR together
Here, k is the maximum number of ranked items inspected for each query. Choose a cutoff that matches the number of items your application can actually send onward.
Recall@k is the number of relevant items found in the first k results divided by the total number of labeled relevant items. This follows the recall definition in Stanford’s Introduction to Information Retrieval.
For q_sharing, retrieving share_roles but not share_limits gives recall 1/2, or 0.5. Finding just one relevant result is a hit, but it is not full recall when two items are labeled relevant.
Reciprocal rank at k is 1 divided by the position of the first relevant result, or zero if none appears within the cutoff. MRR@k averages those values across queries. The Sentence Transformers retrieval evaluator also reports MRR and Recall@k.
A result at position one contributes 1.0; at position two, 0.5. MRR rewards an early useful result but ignores whether later results supply the rest of the evidence. Keep recall beside it for questions needing several sources.
Our example uses binary relevance and averages recall equally across queries. Neither metric checks whether the final generated answer is correct.
3. Run a standard-library Python grader
Save this as evaluate_retrieval.py. Document IDs and rankings below are hand-written fixtures, not benchmark results.
def evaluate(rankings, labels, k):
    if k < 1 or not labels:
        raise ValueError("Use k >= 1 and at least one labeled query")
    rows = {}
    for query_id, relevant in sorted(labels.items()):
        if not relevant:
            raise ValueError("Evaluate no-answer queries separately")
        ranking = rankings.get(query_id, [])
        if len(ranking) != len(set(ranking)):
            raise ValueError("Duplicate document IDs in ranking")
        top = ranking[:k]
        recall = len(set(top) & relevant) / len(relevant)
        rr = next(
            (1 / rank for rank, doc in enumerate(top, 1)
             if doc in relevant),
            0.0,
        )
        rows[query_id] = (recall, rr)
    count = len(rows)
    mean_recall = sum(row[0] for row in rows.values()) / count
    mrr = sum(row[1] for row in rows.values()) / count
    return rows, mean_recall, mrr


labels = {
    "q_export": {"export_csv"},
    "q_reset": {"reset_steps", "reset_limits"},
    "q_sharing": {"share_roles", "share_limits"},
}
rankings = {
    "q_export": ["export_csv", "billing", "profile"],
    "q_reset": ["billing", "reset_steps", "reset_limits"],
    "q_sharing": ["profile", "share_roles", "billing"],
}

if __name__ == "__main__":
    k = 3
    rows, mean_recall, mrr = evaluate(rankings, labels, k)
    for query_id, (recall, rr) in rows.items():
        print(f"{query_id} recall@{k}={recall:.3f} rr@{k}={rr:.3f}")
    print(f"Mean recall@{k}={mean_recall:.3f}")
    print(f"MRR@{k}={mrr:.3f}")
Run it with Python 3:
python3 evaluate_retrieval.py
Expected output:
q_export recall@3=1.000 rr@3=1.000
q_reset recall@3=1.000 rr@3=0.500
q_sharing recall@3=0.500 rr@3=0.500
Mean recall@3=0.833
MRR@3=0.667
The reset query finds both required items, but the first appears at rank two. The sharing query finds only one of its two relevant items. Their reciprocal ranks match, while their recall scores expose the difference.
The function counts a missing ranking as a retrieval failure, rejects duplicate IDs, and refuses empty relevance labels. Questions with no relevant source need a separate test of abstention or clarification; treating their recall as zero would mix different tasks.
4. Replace fixtures with captured search results
Keep labels as the reviewed answer key. Replace rankings with ordered IDs from your real search service. Preserve the order returned by the pipeline, and retain every labeled query even when its result list is empty.
Evaluate the stage that matters. If the generator receives three chunks after reranking and filtering, measure those final chunks, not only the initial search candidates. You can also score the initial stage separately to locate where evidence disappears.
Capture enough context to reproduce a run:
- Collection snapshot and item ID scheme.
- Query set and relevance-label revision.
- Embedding model or lexical-search configuration.
- Candidate count, reranker configuration, filters, and final cutoff.
- Per-query results, elapsed search time, and context size.
Apply the same user permissions in testing as in the application. A relevant document outside the user’s authorized collection must not become a successful retrieval.
5. Compare one change at a time
Run the current retriever and one proposed change against the same frozen questions and labels. You might compare lexical search with a combined lexical-and-vector method, or add a reranker while keeping the first-stage candidate set fixed.
Check per-query differences before celebrating an average. An improvement on export questions can conceal a regression on permission questions. Separate results by task type and language when those distinctions matter to your users.
Define acceptance rules before tuning. For this illustrative documentation workflow, require both sharing sources to appear in the top three for q_sharing, no loss on required regression cases, and search latency within the application’s chosen budget. These are example project rules, not universal deployment thresholds.
For a larger evaluation, reserve reviewed questions that you do not use while tuning. Investigate failures and label disagreements; three fixture questions cannot establish general retrieval quality.
6. Troubleshoot the failure, not just the score
| Observation | What to inspect next |
|---|---|
| Recall is low at every tested cutoff | Missing documents, indexing failures, query wording, or restrictive filters |
| Recall improves when k grows | Ranking quality and the cost of sending extra context |
| MRR is high but recall is low | Missing secondary evidence for multi-source questions |
| Scores jump after changing chunking | Label alignment and the retrieval unit |
| Retrieval looks good but answers remain wrong | Context truncation, conflicting sources, and answer grounding |
More retrieved items are not automatically better for the whole assistant. Track context length and answer quality alongside retrieval scores, using the actual context assembly step.
For background, see how RAG uses enterprise data and recall versus precision.
Takeaway
Start with a reviewed set of questions, stable evidence IDs, and the exact ranked items your assistant receives. Use Recall@k to find missing evidence and MRR@k to inspect the first useful result, then test answer quality separately. Keep the fixtures above as a grader check, not proof that a retriever is ready to deploy.
Sources checked on October 29, 2026. The sample dataset and acceptance rules are illustrative.
Related articles
How to Evaluate AI Agents Before Deployment
10 Essential Books to Master Natural Language Processing
Top 6 Books for Mastering Retrieval Augmented Generation in AI
Understanding the Turing Test and Modern AI Evaluation
Python's Top 10 Uses Explained with Examples
Remove Duplicates from Python Lists: 7 Easy Methods You Should Know
Filtering Lists in Python: From Basic to Advanced
Create and Customize Financial Candlestick Charts in Python
Metrics That Matter: Understanding Hit Rate, MRR, and MMR
Get the Right Data Fast: 7 Best LOOKUP Formulas in Excel
Why Duck Typing Makes Python So Powerful

Mastering 7 Essential Algorithms for Python Data Structures
Latest articles
How to Evaluate AI Agents Before Deployment
AI Agent Memory vs. RAG: What to Store and What to Retrieve
Anthropic's Public Benefit Fund: What Its 5% Share Pledge Means

Giving Robots a Sense of Touch: Tactile Sensors Reach the Fingertips

BT Highlights the Crucial Role of Networks in AI at Mobile World Congress

The Beginner’s Guide to Building RDDs in Apache Spark with PySpark

SSH vs. Telnet: Key Differences in Cyber Security

How Amazon AppFlow Transforms Data Integration Across Cloud Services

AWS S3 Buckets and Security Explained: How Data Stays Safe in the Cloud

A Complete Guide to Apache Sqoop: Features, Architecture, and Operations

What Flipkart Reviews Reveal: A Deep Dive into Sentiment Analysis
