AI Agent Memory vs. RAG: What to Store and What to Retrieve
A support assistant finds the right help article but keeps forgetting that a customer prefers Spanish. Another remembers the customer perfectly but answers from an outdated policy. Both have access to information, yet each is missing a different part of the system.
AI agent memory and retrieval-augmented generation, or RAG, often appear in the same architecture. Understanding their roles helps you decide what an assistant should retain, what it should look up, and which source should settle a disagreement.
What is the difference between agent memory and RAG?
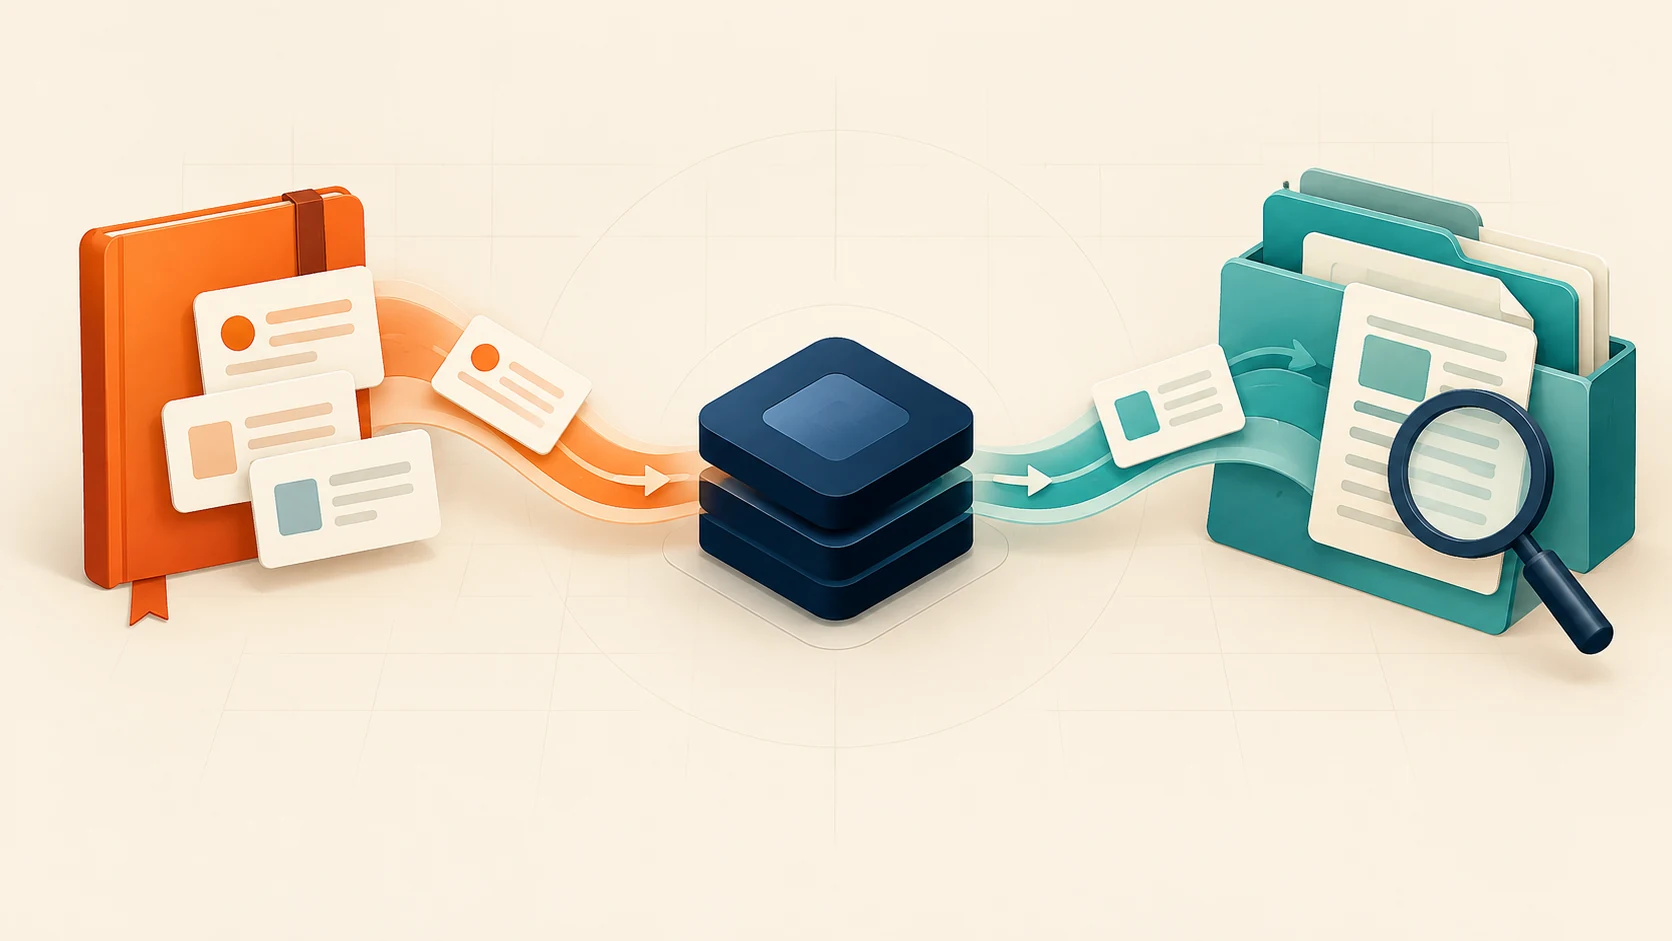
Agent memory preserves information from interactions so it can be used later. Short-term memory tracks an ongoing conversation or task; long-term memory carries selected information across conversations. Short-term describes its scope, so it can still be saved to a database and resumed. LangChain’s memory overview makes this distinction explicit.
RAG retrieves relevant information and supplies it to a model when generating an answer. The source might be documentation, a database, or a search service. It does not have to be a vector database: an existing knowledge system can provide the retrieved context. LangChain’s retrieval guide describes these options.
The two concepts overlap. An assistant can retrieve its stored memories before answering, using a retrieval process similar to one used for documents. Memory adds another design question: which experiences should become records, and how should those records change?
For a support assistant, this is a useful starting arrangement:
| Information | Where it belongs | When to revisit it |
|---|---|---|
| Steps already tried in an open ticket | Current task state | When the ticket changes |
| A customer’s explicit language preference | User memory | When the customer updates it |
| The current return policy | Authoritative knowledge source | When answering a policy question |
| Live delivery status | Order system queried through a tool | When status is requested |
| Whether an action actually succeeded | Transaction record | Before repeating the action |
These are application design choices, rather than a requirement to buy five separate storage products.
How memory and retrieval work together
Consider a hypothetical customer who returns to an assistant after an earlier troubleshooting session. They previously requested Spanish replies and completed a router restart. Now they ask whether a replacement is available.
We would design the next interaction as follows:
- Load the authenticated customer’s language preference.
- Resume the relevant ticket state, including the completed restart.
- Retrieve the applicable replacement policy and check its version.
- Query the product or order system for facts needed to assess the request.
- Explain the next step in Spanish, citing the policy where useful.
This arrangement gives each source a defined job. A language preference controls presentation. A ticket record prevents repetitive troubleshooting. The policy and order system establish the facts needed for the decision.
Google Cloud’s agent architecture overview similarly distinguishes knowledge retrieval, distilled user memory, working context, and transactional records. That separation is helpful when deciding which information can be summarized and which needs an authoritative record.
Store small memories with a traceable source
For the example above, a memory record could look like this:
{
  "tenant_id": "demo-shop",
  "user_id": "demo-user-42",
  "key": "reply_language",
  "value": "es",
  "source_type": "explicit_user_request",
  "source_reference": "conversation-demo-17/message-3",
  "updated_at": "2026-10-22T08:09:00Z"
}
This is an illustrative schema. Its useful feature is the evidence behind the value: someone reviewing the record can see where the preference came from.
In this design, an explicit request to switch languages updates the existing preference. A single Spanish sentence would not automatically establish a permanent preference. The application should make that distinction deliberately.
The tenant and user fields also need server-side access checks. Writing an identifier into JSON alone does not prevent another user from accessing it. Decide how users can inspect, correct, and remove saved preferences before accumulating a large collection.
Why saving every conversation is not enough
A transcript can preserve detail, but an agent still needs to select what belongs in its next model request. Copying the whole archive into every prompt can bury an unresolved question among obsolete plans and irrelevant exchanges.
Anthropic’s context engineering guidance describes two useful techniques: compacting a conversation into a shorter representation, and keeping structured notes outside the context window for later use. It also warns that aggressive compaction can lose details whose importance becomes apparent afterward.
For our support example, a useful note would preserve the active problem, completed troubleshooting, unresolved questions, and references to supporting records. It would avoid converting an uncertain diagnosis into a confirmed fact.
We would also keep the original policy reference alongside any summary. If the policy changes, the assistant needs a route back to the current source. A well-written summary cannot establish whether its underlying information is still valid.
Test corrections and missing information
A memory demo that repeats a saved name proves very little about how the assistant handles changing facts. The LongMemEval research evaluates several abilities, including reasoning across sessions, handling knowledge updates, understanding time, and declining to answer when the history lacks the information.
For a small application, we would begin with these concrete checks:
| Test | Expected behavior |
|---|---|
| The customer changes their language preference | Subsequent replies use the updated preference |
| An old chat conflicts with a newly published policy | The assistant uses the applicable current policy |
| Two customers ask similar questions | Each receives only information they are authorized to access |
| A requested detail was never provided | The assistant asks for it or states that it is unknown |
| A ticket resumes after a restart | Completed steps and unresolved questions remain distinguishable |
Record both the retrieved material and the final answer during evaluation. That makes it easier to distinguish missing evidence from an answer that misuses evidence. Compare the same cases with memory enabled and disabled; personalization should help without reducing factual accuracy.
Start with the information your task needs
For a documentation assistant, retrieval and conversation state may be sufficient. A returning-customer assistant may also benefit from a few explicit preferences. A workflow agent needs dependable records of completed actions before it needs an extensive archive of remembered impressions.
Choose one recurring failure, such as repeated troubleshooting or a forgotten preference, and test whether a small memory fixes it. Add more retained information only when you can explain how the agent will use, update, and verify it.
For background, read our guides to RAG and enterprise data and semantic memory for AI assistants.
Sources checked on October 22, 2026. The support scenario, record format, and suggested application checks are illustrative editorial guidance.
Related articles

Lightweight Agno Framework for Fast Multimodal AI Agent Creation

Lack of Agreement on AI Rules in U.S., EU Gives China a Leg Up

15 Best AI Tools for Startup Founders
ChatGPT Works Well—But One Change Could Make It Work Better

How to Use AI Brand Voice Generator to Preserve Channel-Specific Voices
Anthropic's Public Benefit Fund: What Its 5% Share Pledge Means

AWS Seeks to Teach Executives About Generative AI
The Long-Term Solution to Addressing Bias in AI Systems

Top 11 Companies Hiring for AI Jobs in 2025
Google Aims to Boost Productivity with AI Agent Tool

12 Top Resources to Build an Ethical AI Framework

Orchestrating AI: the Transition From Solo Acts to a Complete Symphony
Latest articles
How to Evaluate RAG Retrieval With Recall@k and MRR
How to Evaluate AI Agents Before Deployment
Anthropic's Public Benefit Fund: What Its 5% Share Pledge Means

Giving Robots a Sense of Touch: Tactile Sensors Reach the Fingertips

BT Highlights the Crucial Role of Networks in AI at Mobile World Congress

The Beginner’s Guide to Building RDDs in Apache Spark with PySpark

SSH vs. Telnet: Key Differences in Cyber Security

How Amazon AppFlow Transforms Data Integration Across Cloud Services

AWS S3 Buckets and Security Explained: How Data Stays Safe in the Cloud

A Complete Guide to Apache Sqoop: Features, Architecture, and Operations

What Flipkart Reviews Reveal: A Deep Dive into Sentiment Analysis
