Choose AI Review Thresholds With Coverage and Error Rates
Sending uncertain AI predictions to a person sounds efficient—until the review queue exceeds the team’s capacity. A stricter threshold can reduce automated mistakes while creating more work than anyone can process.
Build a local threshold comparison for an AI request tagger. You will measure automated coverage, errors among accepted predictions, and review workload together. Python 3.10 or later suffices; the synthetic fixtures need no packages, API calls, or private data.
1. Separate prediction from permission to automate
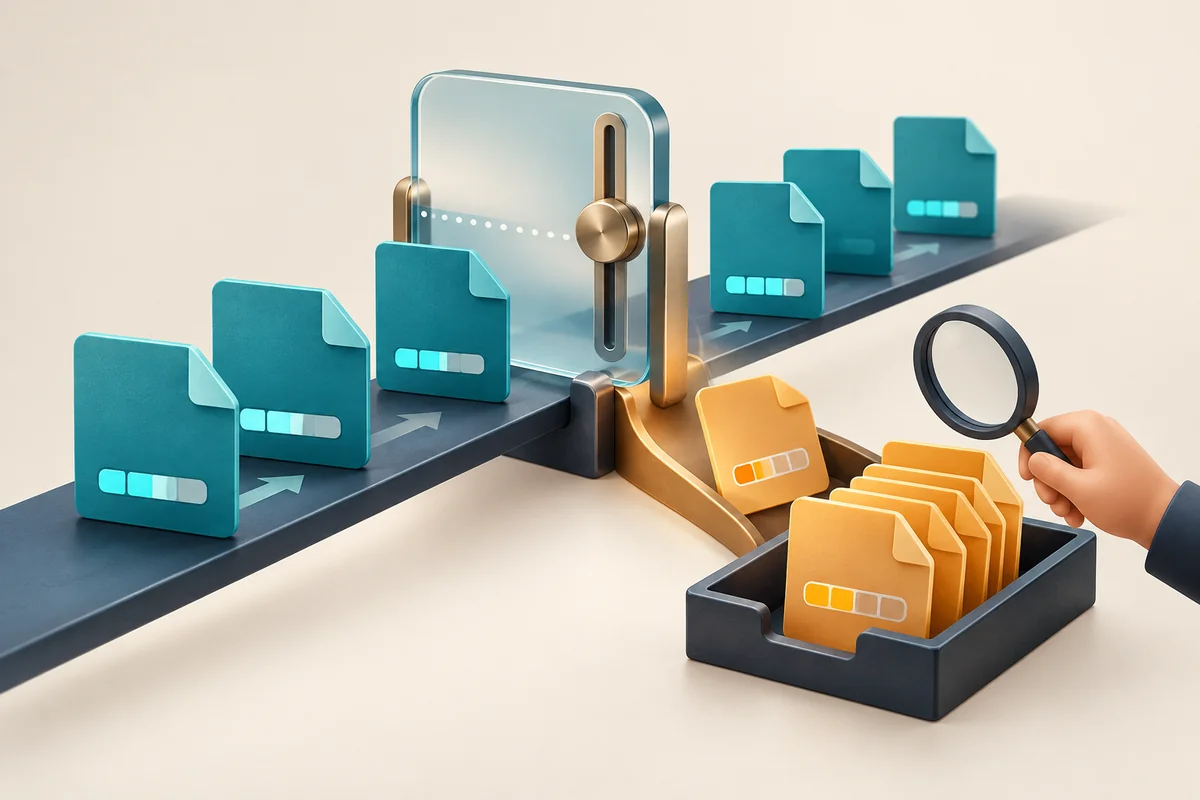
The tagger chooses question or bug. A separate selection score determines whether to automate that prediction or abstain and request review. Abstention does not choose a third label or imply that a reviewer will be correct.
This is the coverage–risk trade-off studied in selective classification. Unlike our ticket-routing evaluation, this exercise asks which predictions to accept, not just which category was chosen.
Here, higher scores mean greater selection confidence on a scale from zero to one. They are synthetic ranking signals, not calibrated probabilities. A chatbot saying “0.95 confidence” does not establish 95% correctness. Scikit-learn’s calibration guide explains what calibrated probabilities require; our Brier-score tutorial examines probability quality separately.
2. Define the denominators and review budget
For each threshold, accept predictions whose score is greater than or equal to it.
- Coverage: accepted requests divided by all requests.
- Selective error: incorrect accepted predictions divided by accepted predictions.
- Review count: all requests minus accepted requests.
With no accepted requests, selective error is undefined, not zero. Keep that result explicit.
For this eight-request exercise, require error at most 0.10 and no more than four reviews. These are illustrative constraints, not production standards. In practice, budget reviews against arrivals and staffing over a defined time window.
3. Run the threshold comparison
Save this as review_thresholds.py. Each ID maps to a reviewed label, the frozen prediction, and its selection score. Match real records by ID before adapting the fixture.
import math

# request_id: (reviewed label, predicted label, selection score)
ROWS = {
    "r1": ("question", "question", 0.98),
    "r2": ("bug", "bug", 0.95),
    "r3": ("bug", "question", 0.90),
    "r4": ("question", "question", 0.85),
    "r5": ("bug", "bug", 0.75),
    "r6": ("question", "bug", 0.65),
    "r7": ("question", "question", 0.55),
    "r8": ("bug", "question", 0.40),
}
LABELS = {"question", "bug"}


def unit_score(value):
    return (type(value) in (int, float)
            and math.isfinite(value) and 0 <= value <= 1)


def evaluate(rows, threshold):
    if not rows or not unit_score(threshold):
        raise ValueError("nonempty rows and threshold in [0, 1] required")
    accepted = errors = 0
    for actual, predicted, score in rows.values():
        if actual not in LABELS or predicted not in LABELS:
            raise ValueError("unknown label")
        if not unit_score(score):
            raise ValueError("score must be finite and in [0, 1]")
        if score >= threshold:
            accepted += 1
            errors += actual != predicted
    review = len(rows) - accepted
    coverage = accepted / len(rows)
    error = errors / accepted if accepted else None
    return accepted, review, coverage, error


if __name__ == "__main__":
    for threshold in (0.00, 0.80, 0.95, 1.00):
        accepted, review, coverage, error = evaluate(ROWS, threshold)
        ready = error is not None and error <= 0.10 and review <= 4
        rate = "NA" if error is None else f"{error:.3f}"
        print(f"t={threshold:.2f} auto={accepted} review={review} "
              f"coverage={coverage:.3f} error={rate} "
              f"gate={'PASS' if ready else 'HOLD'}")
Run:
python3 -B review_thresholds.py
Expected output:
t=0.00 auto=8 review=0 coverage=1.000 error=0.375 gate=HOLD
t=0.80 auto=4 review=4 coverage=0.500 error=0.250 gate=HOLD
t=0.95 auto=2 review=6 coverage=0.250 error=0.000 gate=HOLD
t=1.00 auto=0 review=8 coverage=0.000 error=NA gate=HOLD
4. Validate quality and workload together
The no-abstention baseline accepts all eight requests and makes three errors: 0.375. At 0.80, four requests are accepted, but one is wrong, so error is 0.250. At 0.95, neither accepted prediction is wrong, yet six requests need review—above the budget.
None of the displayed thresholds passes both requirements. Rejecting everything also holds: NA cannot establish prediction quality. Zero observed errors on two cases is not evidence of reliable production performance.
As a positive control, change only r3’s predicted label to bug. The 0.80 row should show four accepted, four reviewed, error 0.000, and PASS. Restore the fixture afterward. Empty input, unknown labels, nonfinite scores, and out-of-range scores should raise ValueError; booleans are also rejected as scores.
The original script exits 0 with empty standard error. HOLD is a report, not a shell-level deployment blocker.
5. Troubleshoot before choosing a threshold
- Error increases with a stricter threshold: inspect confidently wrong cases. Coverage falls as the threshold rises; error need not fall monotonically.
- Review workload explodes: do not silently discard abstentions. Improve the model, narrow eligible requests, or increase review capacity.
- Scores mean different things: use confidence in the selected label, not probability of a fixed positive class. Check score behavior on reviewed examples.
- Results look suspiciously good: choose thresholds on separate validation records, freeze the choice, then evaluate untouched test records. Scikit-learn warns against reusing training data for threshold tuning.
On larger samples, report accepted counts and errors by class and language. Track reviewer delays and mistakes separately: this script does not measure final human-assisted accuracy. After changing a prompt or model, rerun a paired regression comparison and recheck the frozen threshold.
Practical takeaway
Choose an automation policy, not just an impressive confidence cutoff. Keep coverage, accepted-case errors, and review capacity visible; if no threshold meets the requirements, keep the workflow under review.
Related articles
Evaluate AI Ticket Routing With a Confusion Matrix

Lack of Agreement on AI Rules in U.S., EU Gives China a Leg Up

15 Best AI Tools for Startup Founders

How to Use AI Brand Voice Generator to Preserve Channel-Specific Voices

Lightweight Agno Framework for Fast Multimodal AI Agent Creation
Compare AI Prompt Versions With a Python Regression Test
Find Train/Test Text Overlap Before Evaluating an AI Model
Evaluate AI Transcription Accuracy with Word Error Rate
Evaluate AI Probability Forecasts With the Brier Score in Python
Anthropic's Public Benefit Fund: What Its 5% Share Pledge Means

AWS Seeks to Teach Executives About Generative AI

Top 11 Companies Hiring for AI Jobs in 2025
Latest articles
Check AI Translations for Broken Placeholders With Python
Compare AI Prompt Versions With a Python Regression Test
Reject Ambiguous AI JSON Before Automation With Python
Evaluate AI Probability Forecasts With the Brier Score in Python
Find Train/Test Text Overlap Before Evaluating an AI Model
Preview AI File-Renaming Plans Before Touching Files
Test AI-Generated Regex with Small Python Fixtures
Test AI-Generated SQL with Small SQLite Fixtures
Evaluate AI Transcription Accuracy with Word Error Rate
Evaluate AI Ticket Routing With a Confusion Matrix
How to Evaluate RAG Retrieval With Recall@k and MRR